Building observability into production LLM applications is how teams stop guessing why quality slipped last Tuesday. Uptime monitors tell you the API responded. They do not tell you that retrieval returned the wrong policy, that a prompt change doubled cost, or that a silent tool failure caused polite but useless answers. Production AI needs traces, quality signals, and business metrics wired together from day one.
QuantaloomAI treats observability as product infrastructure — the same seriousness we apply to auth and data pipelines. If you cannot explain a bad answer with evidence, you do not have a production system; you have a demo with traffic.
Why LLM observability differs from classic APM
Traditional APM tracks latency, error rates, and saturation. LLM apps add:
- Non-deterministic outputs: the same input can yield different text; "correctness" needs evals, not status codes
- Multi-hop traces: retrieval, rerank, prompt assembly, model call, tool use, and post-validation each matter
- Cost as a reliability signal: token spikes often precede quality regressions or abuse
- Semantic failures: 200 OK responses that hallucinate, leak PII, or violate policy
Teams that only alert on HTTP 5xx miss the failures customers actually feel. Pair classic infra metrics with semantic ones — groundedness scores, tool success rates, escalation rates, and human override frequency.
The observability stack that ships
Request traces end to end
Every user turn should produce a trace ID linking: auth context, retrieved chunks (IDs + scores), prompt template version, model + parameters, tool calls, latency per hop, and final response metadata. Store redacted payloads with retention rules — full transcripts forever is a compliance risk.
Quality evals on a schedule
Offline evals catch regressions before deploy. Online sampled evals catch drift after. Score groundedness, refusal correctness, and task completion. Connect this to the discipline in evaluation pipelines that ship — observability without evals is logging theater.
Cost and latency budgets
Track cost per successful outcome, not only cost per token. A cheaper model that doubles retries is more expensive. Alert when p95 latency or cost-per-session crosses thresholds for a tenant or feature flag.
Business outcome joins
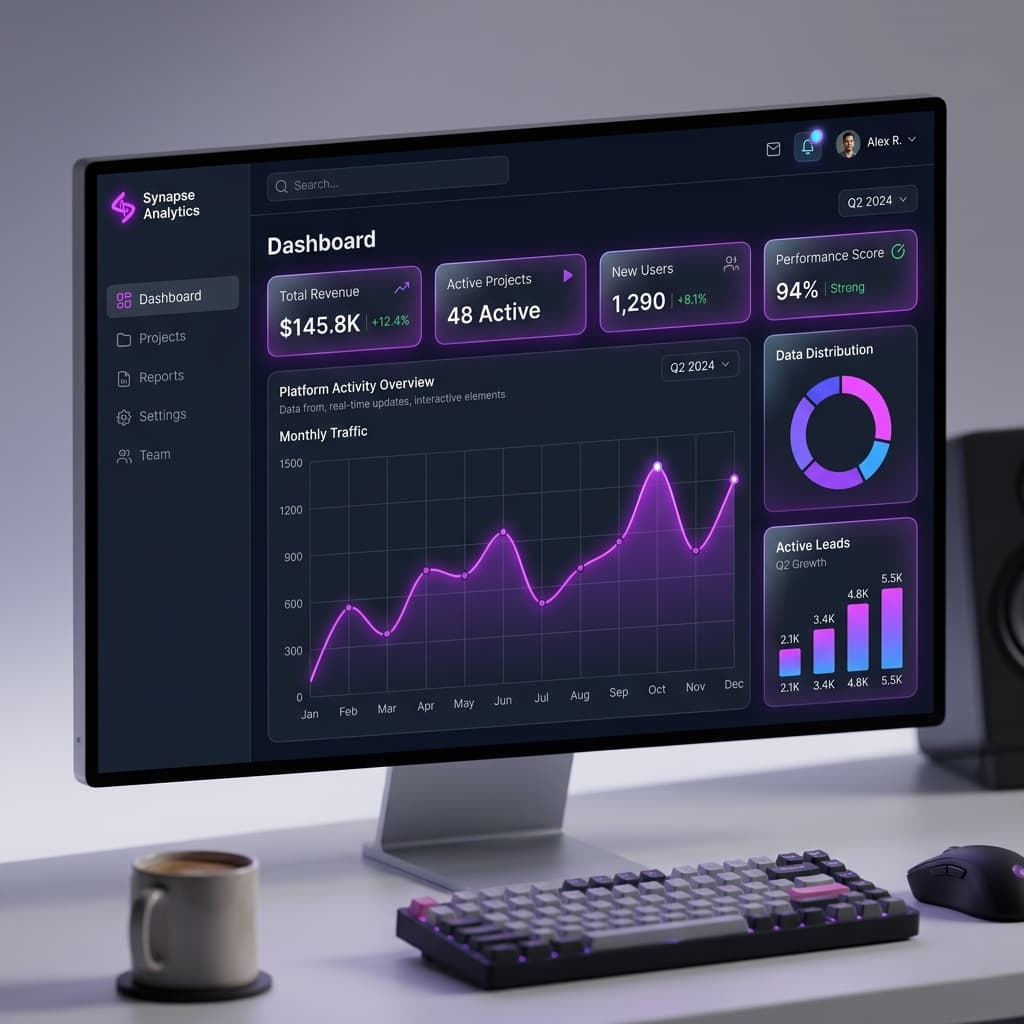
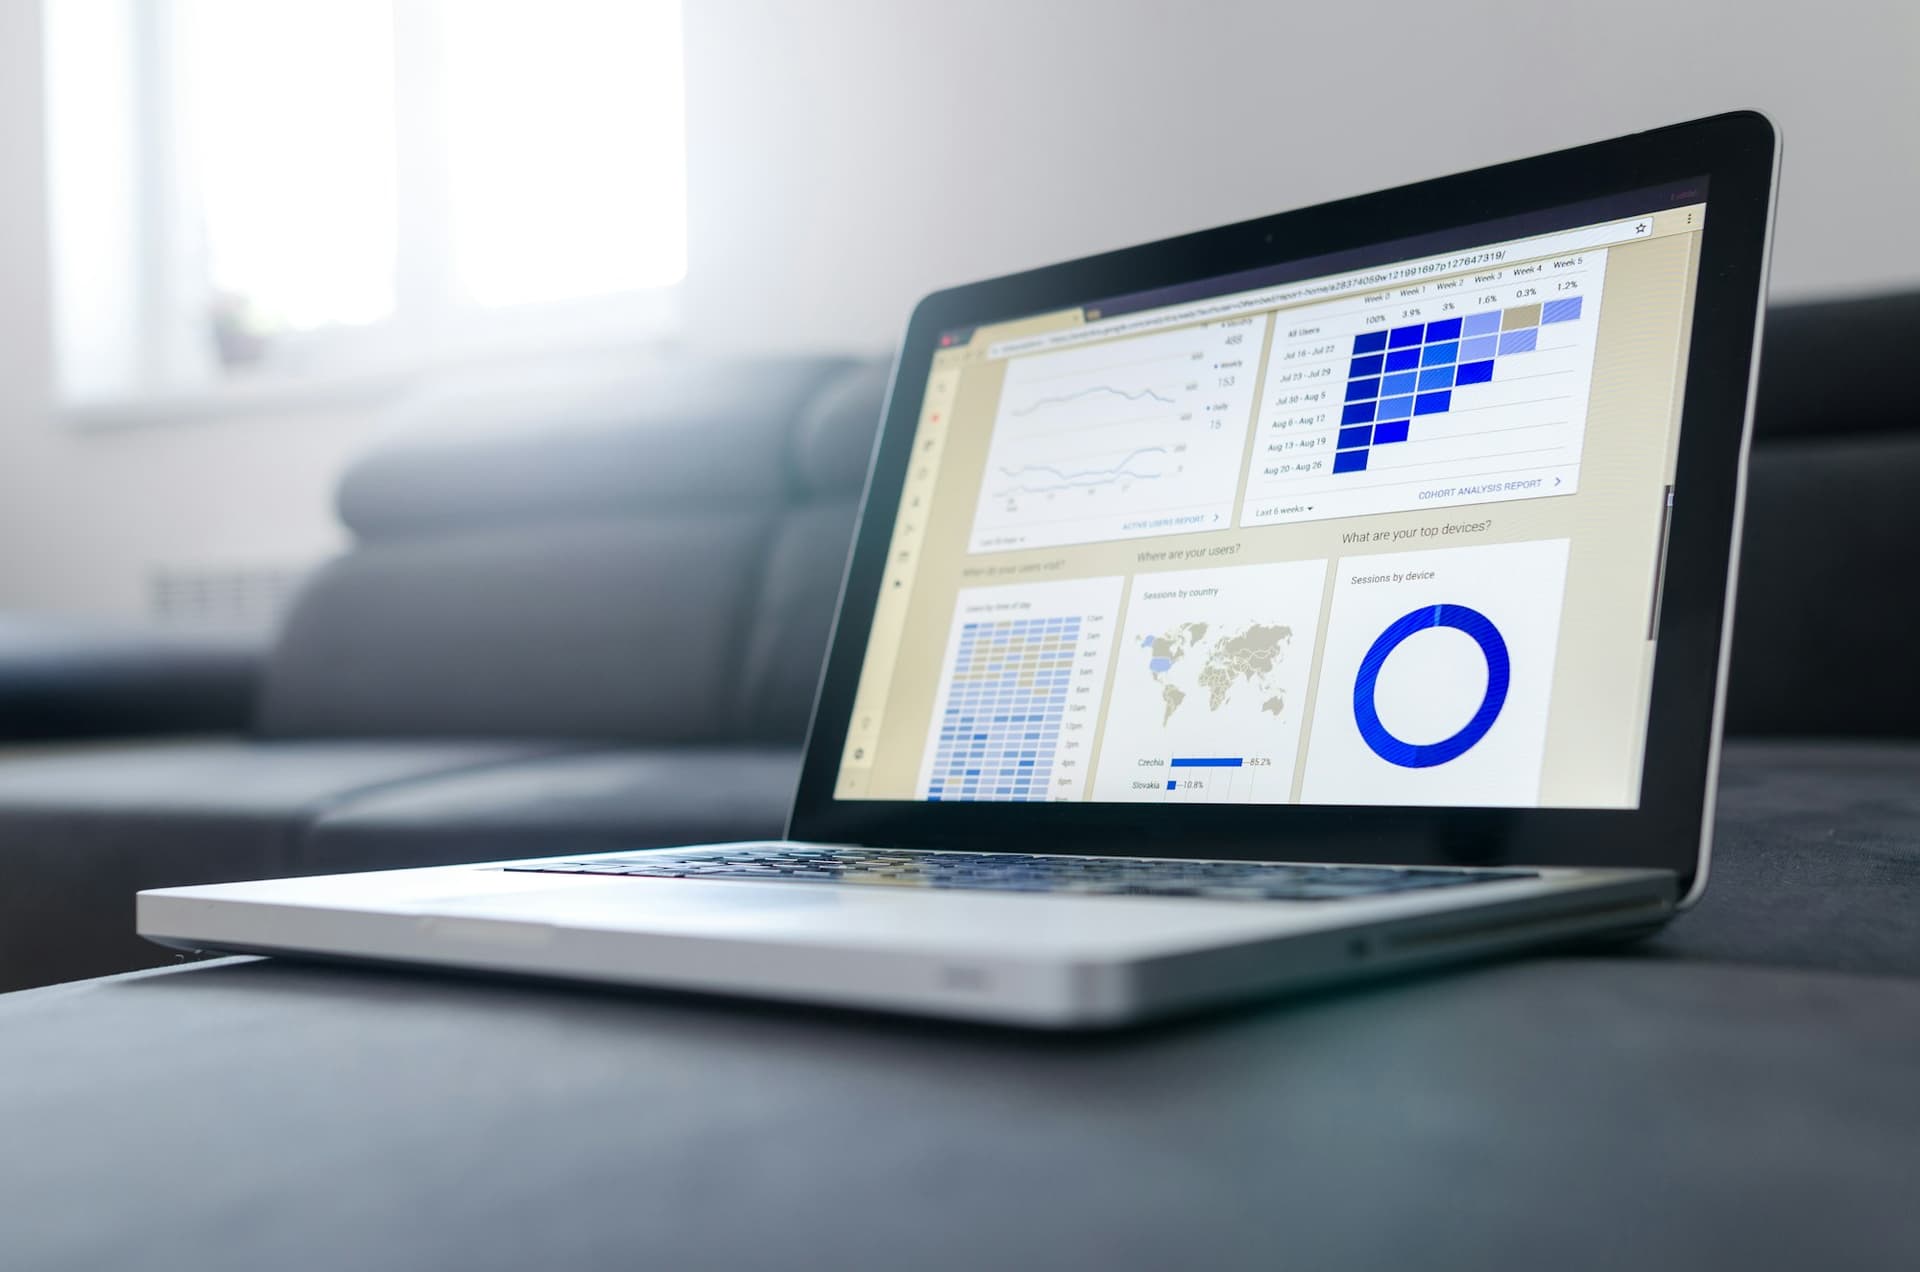
Join AI traces to tickets closed, orders updated, or appointments booked. Executive dashboards need outcome language — see AI analytics dashboards executives actually use. Engineering needs the drill-down to the failing span.
Practical signals and alerts
Minimum production alerts:
1. Tool failure rate > baseline for 15 minutes 2. Groundedness / citation miss rate spike 3. Cost per session +40% vs weekly median 4. Escalation or thumbs-down rate spike by intent 5. Retrieval empty-result rate for critical indexes
Do not page humans for every low-confidence answer. Page on systemic drift. Queue low-confidence samples for review queues instead.
Data engineering as the foundation
Observability dies when logs are inconsistent. Normalize event schemas early: actor, tenant, intent, span type, model version, retrieval set hash. QuantaloomAI data engineering work often precedes flashy model upgrades because dirty events make dashboards lie.
For multi-tenant SaaS platforms, isolate traces by tenant and enforce that support staff can only see accounts they are permitted to access. Observability must respect the same RBAC as the product.
Incident playbooks for LLM systems
When quality drops:
1. Freeze prompt/model deploys 2. Compare retrieval hit rates and chunk freshness against yesterday 3. Diff prompt template versions and tool schemas 4. Sample failing traces by intent — look for shared missing documents 5. Roll back or feature-flag the change; publish a customer-safe status note if external
Document known failure modes: stale index, embedding model swap, vendor outage, prompt injection spike. Link each to a runbook owner. Platforms like NeuralDesk and complex ops builds only stay trustworthy when incidents are rehearsed.
How to start in two weeks
Week one: instrument traces + cost + tool success. Week two: add a 50-case golden eval and one executive outcome metric. Avoid boiling the ocean with twenty quality rubrics before the first dashboard ships.
Privacy and retention for AI logs
Observability creates a new sensitive data store. Decide what is redacted at ingest: emails, account numbers, clinical notes, authentication secrets. Prefer storing chunk IDs and hashes over raw retrieved text when possible. Set retention windows that match legal requirements — often shorter for prompts than for aggregate metrics.
Access to traces should follow the same RBAC as the product. A support engineer debugging one tenant must not browse every conversation across the fleet. Break-glass access deserves its own audit event. These practices overlap with compliance-ready AI and should be designed together, not bolted on after a security questionnaire arrives.
Team rituals that keep signals useful
Dashboards rot without owners. Run a weekly quality review: top failing intents, cost outliers, and one deep dive into a cluster of bad traces. Assign action items to retrieval, prompt, or tool owners. Monthly, prune noisy alerts and add golden-set cases from the worst production failures.
Product managers should attend at least twice a month so engineering metrics stay tied to customer outcomes. When leadership only sees uptime green lights, they approve risky expansions. When they see groundedness and cost-per-outcome, they fund the right work — including SaaS platform investments that make tenant isolation and metering first-class.
Building observability into production LLM applications is not optional polish — it is how you earn the right to expand scope. QuantaloomAI AI product development engagements include observability milestones beside feature milestones so "it works in staging" never becomes "we hope production is fine."
*Written by Sharjeel Ahmed, QuantaloomAI. Book a briefing to harden observability on your LLM stack.*